 timothy
12e5c3d26f
PR Gates / CI image pin matches docker/ci (pull_request) Successful in 10s
PR Gates / Docs update reminder (pull_request) Successful in 13s
PR Gates / decisions lifecycle (pull_request) Successful in 22s
Build ErsatzTV Image / API docs in sync (OpenAPI + endpoint index) (pull_request) Successful in 16s
Build ErsatzTV Image / Formatting (changed .cs conform to .editorconfig) (pull_request) Successful in 13s
Build ErsatzTV Image / Functional E2E (curl contracts) (pull_request) Successful in 5m44s
Build ErsatzTV Image / EF migration integrity (SQLite + MySql) (pull_request) Successful in 15m11s
Build ErsatzTV Image / Build & test (.NET) (pull_request) Successful in 20m14s
Build ErsatzTV Image / Build & push image (amd64) (pull_request) Has been skipped
Timothy asked why the kickoff handoff doc stores historical narrative when
it should be instructions. It shouldn't — its own lore section is chartered
as "STANDING workflow/orchestration rules only" with the why belonging in
docs/decisions.md. But an inventory of every bullet against the decision
corpus inverted the premise: only ~8 of ~38 were actually covered. 19 had
no record anywhere and 11 more were half-covered, so that single file was
the ONLY copy of the mandatory review rubric, the whole CI-triage
vocabulary, the build-concurrency policy, the H12 session-end audit, and
the plumbing-merge recipe. Pruning first would have destroyed them.

So the records come first. New topic file docs/decisions/workflow-process.md
carries 32 records (ci.*, process.*, testing.*) covering every NONE and
PARTIAL the inventory found, including the Gitea `?milestones=` no-op bug
whose only copy was the archived selector section this prune deletes.

Only then the prune: HARD CONSTRAINTS and the lore section become one- or
two-line rules, each citing the decision key that holds its evidence, and
the 40-line "Archived — do not follow" section is gone. 636 -> 353 lines,
with every cited key verified to resolve against the corpus.

The aggregate corpus budget is re-baselined 4800 -> 5600 with the reason in
the code: the corpus grew because knowledge MOVED into it, which is the
system working, not drift.

refs #542
ErsatzTV
ErsatzTV lets you transform your media library into a personalized, live TV experience - complete with EPG, channel scheduling, and seamless streaming to all your devices. Rediscover your content, your way.


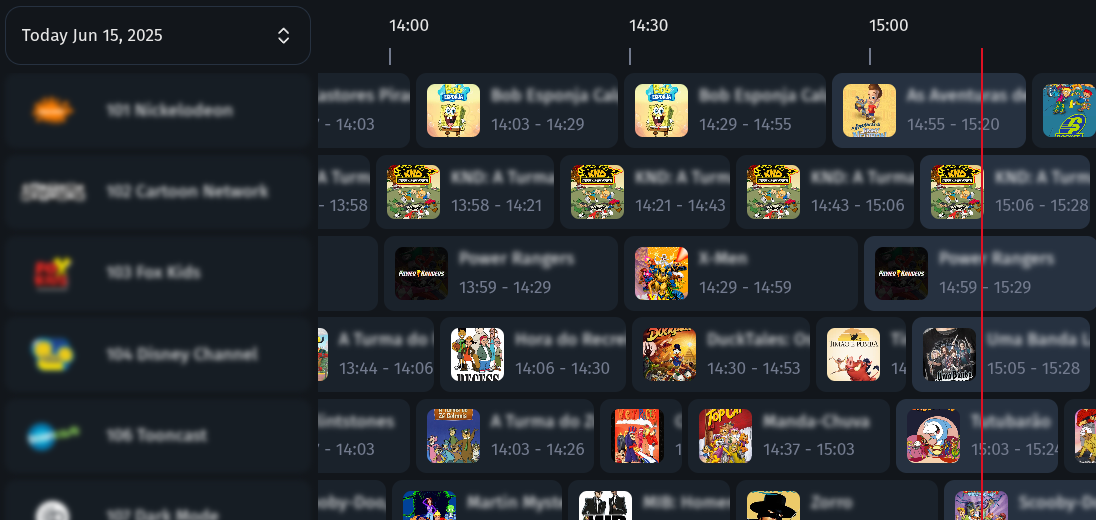
How It Works
- Install ErsatzTV: Download and set up the server on your system.
- Add Your Media: Connect your media libraries and collections.
- Create Channels: Design and schedule your own live channels.
- Stream Anywhere: Watch on any device with IPTV and EPG support.
Key Features
- Custom channels: Create and schedule your own live TV channels.
- IPTV & EPG: Stream with IPTV and Electronic Program Guide support.
- Hardware Transcoding: High-performance streaming with hardware acceleration (NVENC, QSV, VAAPI, AMF, VideoToolbox)
- Media Server Integration: Connect Plex, Jellyfin, Emby and more.
- Music & Subtitles: Mix music videos and enjoy subtitle support.
- Open Source: Free, open, and community-driven project.
Documentation
Documentation is available at ersatztv.org.
License
This project is inspired by pseudotv-plex and the dizquetv fork and is released under the zlib license.